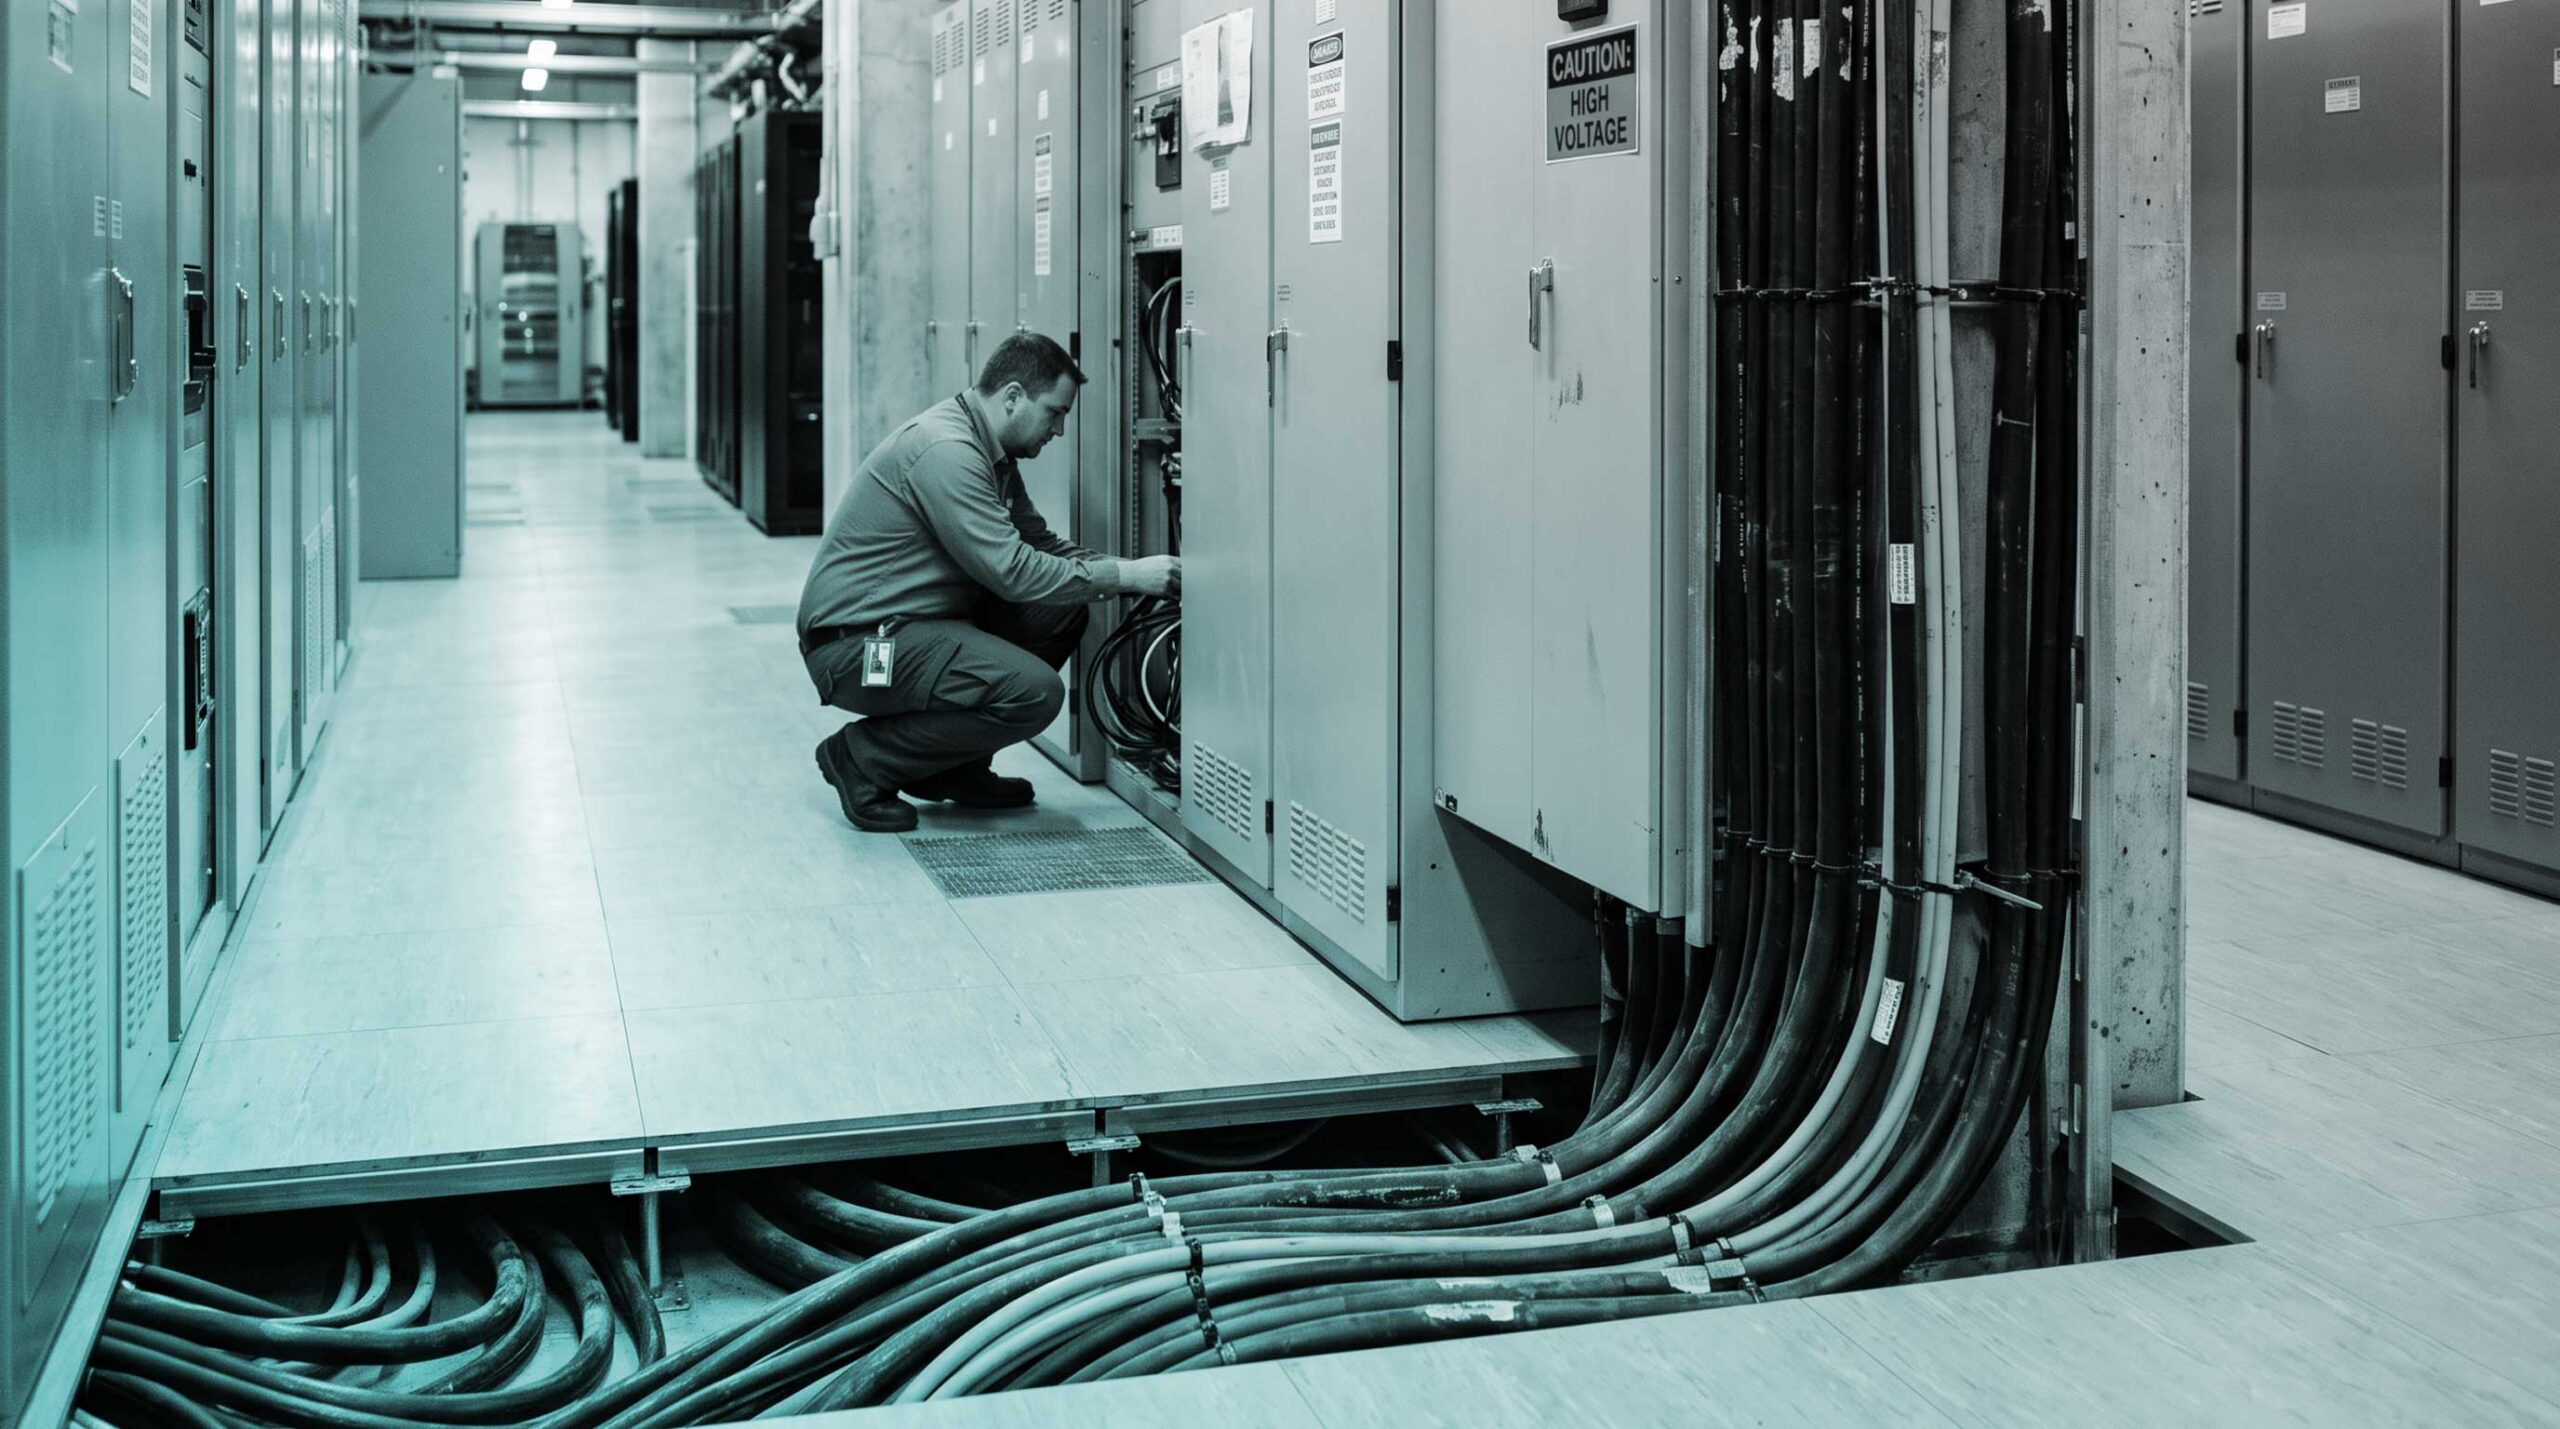
Most data center power problems are not equipment failures. They are design and planning decisions that looked reasonable at the time: sizing to nameplate ratings, forgetting the continuous load derate, treating a 2N pair as additive capacity, running out of breaker positions rather than amps, and leaving the distribution architecture until after the layout is fixed. The ten data center power distribution mistakes below are avoidable, and most cost far more to correct than to prevent.
1. Sizing to nameplate ratings
Nameplate ratings describe what a power supply could theoretically draw with every option fitted and everything at maximum. Real sustained draw is commonly well below that.
Designing to nameplate means the rack fills on paper long before it fills electrically, and the facility ends up supporting far less equipment than its infrastructure could carry.
What to do instead: use manufacturer power calculators for the specific configuration, measured draw from identical equipment already in service, or metered data from a comparable rack. Where none exists, use nameplate but record the assumption so it gets revisited once real measurements are available.
2. Forgetting the continuous load derate
Electrical codes generally require circuits carrying continuous loads, meaning loads running at maximum for three hours or more, to be limited to 80 percent of their rating. Essentially all IT equipment qualifies.
A 30A circuit therefore provides 24A of usable capacity, not 30A. Skipping this step produces racks that work fine on a spreadsheet and trip in service.
What to do instead: apply the derate at the start of the sizing calculation rather than as a check at the end, and confirm the applicable requirement with the engineer of record for your jurisdiction and code edition.
3. Treating a 2N pair as additive capacity
A rack fed by two 30A circuits in a 2N arrangement does not have 48A of usable capacity. It has 24A, because each side must be able to carry the entire load alone.
This is the whole point of 2N, and sizing as though the feeds add together quietly removes the redundancy that was paid for. The problem only becomes visible when one side actually goes down, which is the worst possible moment to discover it.
What to do instead: size each side of a 2N feed to carry the full load independently, and treat the pair’s usable capacity as one side’s worth.
4. Running out of positions rather than amps
Capacity planning tends to track amps and kW. What actually runs out first is frequently physical: breaker positions in a panel, outlets on a rack PDU, or tap-off positions on a busway run.
The result is stranded capacity, where power exists upstream but cannot reach the equipment that needs it. Adding more upstream capacity does not fix it, because the constraint was never upstream.
What to do instead: track positions and outlets alongside amperage in capacity planning, and check position counts at the box or breaker size you actually intend to use rather than the smallest available.
5. Leaving the distribution architecture until after the layout
At conventional densities, power distribution is a component decision that can follow the floor plan. At high density it constrains the floor plan, because cable volume, containment routes and access clearances all compete for the same space.
Deciding the architecture after racks are positioned means retrofitting distribution into a layout that was not designed for it, which is consistently the most expensive way to arrive at the same answer.
What to do instead: settle whether distribution runs overhead or under floor, and whether power is distributed to the room, the row or the rack, before the layout is fixed.
6. Assuming A and B feeds are independent when they are not
Dual-corded equipment fed from two circuits that share an upstream panel is not on a 2N feed. It has two cords and one point of failure.
This happens most often in retrofits, where A and B labelling gets applied to circuits that were never genuinely independent, and in incremental expansions where a new circuit is taken from whichever panel had space.
What to do instead: trace both paths back to the point where redundancy actually begins, and verify independence at every stage rather than trusting the labelling.
7. Ignoring phase balance
On a three-phase rack PDU, outlets are assigned to phase pairs. Loading equipment onto whichever outlet happens to be unused produces uneven distribution across phases.
A PDU heavily loaded on one phase and lightly loaded on another will trip protection while apparently having capacity remaining. The wasted capacity can be substantial.
What to do instead: assign outlets deliberately with phase in mind, and check per-phase current after installation and after any equipment change. Most intelligent rack PDUs report this directly.
8. Specifying by manufacturer instead of by configuration
Naming a specific model with a nominal ‘or approved equal’ is efficient when supply is plentiful. When it is not, it hands the project schedule to whichever manufacturer happened to be named.
It also makes substitution expensive. If that supplier’s delivery slips, the alternative is a redesign rather than a swap.
What to do instead: define what the equipment must do — voltage class, fault rating, footprint, interrupting capacity, coordination requirements — and let delivery date compete alongside price. It takes more engineering effort up front and it preserves options later.
9. Sizing to today’s density
Rack density has risen steadily and continues to. Distribution sized exactly to current requirements is frequently full within a refresh cycle.
The cost of that is not just the additional equipment. It is doing the work in a live room, which is slower, riskier and often requires a maintenance window that is difficult to obtain.
What to do instead: decide the growth allowance deliberately, sized against how disruptive adding capacity later would be. Where adding a circuit means a shutdown, headroom is cheap insurance. Where distribution can be extended live, less is needed.
10. Not checking the physical connection
The most avoidable failure of all: equipment that is correctly rated and physically cannot connect.
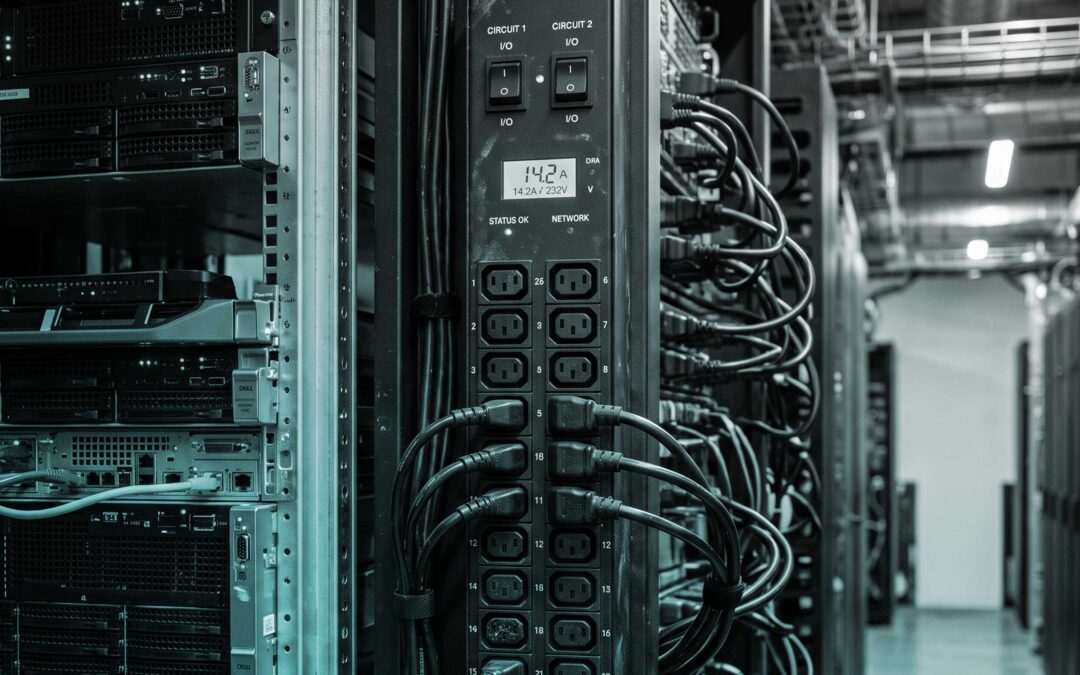
NEMA and IEC designations encode voltage, current and configuration, and a mismatch cannot be safely adapted on site. Cord lengths that do not reach, PDUs mounted where the rear channel is congested, and outlet counts that ran out before amperage did all belong in the same category.
What to do instead: verify receptacle type at both ends, count outlets as well as amps, and confirm cord length and entry position against the actual rack and its cable management before the order goes out.
The pattern behind most data center power distribution mistakes
Eight of the ten come down to the same thing: a decision made with a number that was easier to get than the number that mattered. Nameplate instead of measured draw. Circuit rating instead of usable capacity. Amps instead of positions. Today’s density instead of the refresh cycle.
The other two, independence of A and B feeds and physical connection checks, come from trusting a label rather than verifying the thing itself.
Neither pattern is solved by better equipment. Both are solved by asking, at design stage, what would have to be true for this to be wrong.
Frequently asked questions
What is the most common data center power sizing mistake?
Sizing to nameplate ratings rather than measured draw. Nameplate describes a theoretical maximum with every option fitted, and real sustained draw is commonly much lower. Designing to nameplate strands capacity, because racks fill on paper long before they fill electrically. Close behind it is forgetting the continuous load derate, which limits circuits to 80 percent of their rating and is what causes racks that look fine on a spreadsheet to trip in service.
Why does a data center run out of power capacity before it runs out of space?
Usually it has not run out of power at all. It has run out of positions: breaker slots in a panel, outlets on a rack PDU, or tap-off positions on a busway run. This is called stranded capacity, and it means power exists upstream but cannot physically reach the equipment that needs it. Adding upstream capacity does not resolve it, because the constraint was never upstream.
How do I know if my A and B power feeds are really independent?
Trace both paths back from the rack to the point where redundancy is intended to begin, and check that they do not share a panel, breaker or upstream device anywhere along the way. Labelling is not evidence. This matters most in retrofits and incremental expansions, where A and B labels are sometimes applied to circuits that were never separated, leaving dual-corded equipment with two cords and a single point of failure.
What happens if a three-phase rack PDU is unbalanced?
The heavily loaded phase reaches its protection limit while the others still have capacity, so the PDU trips despite appearing to have headroom overall. The unused capacity on the lighter phases is wasted. Assigning outlets deliberately with phase in mind, and checking per-phase current after installation and after any equipment change, avoids it. Most intelligent rack PDUs report per-phase current directly.
Next step
Trilogy engineers and supplies data center power distribution, from switchboards and busway through to rack-level distribution. If you want a design reviewed before it is built rather than after, we are happy to look at it.
You can also follow Trilogy on LinkedIn.